- Home
- Technical Writing
- STAR story generator on Azure
A STAR Story Generator on Azure: Prompting GPT-4o-mini for JSON and Parsing What Comes Back
By Jack Jin · April 13, 2025 · Updated October 4, 2026 · 7 min read
The STAR Story Generator turns feedback into STAR stories (Situation, Task, Action, Result) with GPT-4o-mini on Azure AI Foundry, served from one Azure Functions app. This walks through the prompt that pins down each part of a story, the parser that copes when the model doesn't send clean JSON, and one reply that gets past its validation. I vibe coded it in a day in April 2025 with five AI tools, and how they ranked is at the end.
What changed
da712d5, the last commit of that Sunday.What changed since I wrote this
I came back to the repo twice in 2026. In April I gave the page a loading state, an error banner instead of a browser alert, and a better copy button (98bf9ea). In May I added GitHub Actions: a build and test run on every push, and a deploy to the Function App that signs in to Azure with OIDC instead of a stored password (c1cf6b4). Both workflows passed on May 9, 2026. That passwordless pattern is the subject of my June 2025 article on Azure RBAC for AI agents.
The tool ranking below is a snapshot of April 2025, and I've left it as I wrote it. The tools have moved a lot since. For a newer comparison, see four frontier models given one prompt, from July 2026.
1. What the app does and how it's wired
The app takes feedback you've received and writes STAR stories from it, the kind you'd prepare for an interview or a self-review. You upload a CSV of feedback, or flip a toggle to use the sample file, which is fictional feedback for a UX designer. Then you pick who the story is for: your top five to prepare, leadership, technical, sales, a colleague, a client, an employer, or a custom prompt. GPT-4o-mini writes the stories and the page lets you step through them.

The deployed app, from the screenshot in my April 2025 post, running the fictional sample data. The story on screen is generated, not real.
All of it runs on one Azure Functions app with three HTTP functions. One serves the page, its CSS and its scripts. One parses the CSV. One generates the stories, and that one is split into a controller, a service, a prompt builder, an Azure OpenAI client and a response processor. That split came partway through the build, in a commit called "Refactoring the open ai integration into an MVC pattern".
DefaultAzureCredential, no API key in the request.da712d5. Steps 4 to 6 happen inside a single function call.One detail from the code: the Azure OpenAI client authenticates with DefaultAzureCredential and a bearer token. The README still lists an AZURE_OPENAI_KEY setting, and the code reads it, but nothing uses it. I picked GPT-4o-mini for cost. In April 2025 I noted it at $0.15 per million input tokens; check Azure's pricing page for today's number. My Azure takeaway at the time: Azure AI Foundry's integration with base and fine-tuned models made deploying this surprisingly straightforward.
2. How the prompt asks for a STAR story
The prompt does most of the work. Its base spells out each part of STAR, down to the sentence count:
promptBuilder.js, lines 18 to 31
    const basePrompt = `You are an expert in crafting professional STAR (Situation, Task, Action, Result) stories.
    Create compelling and authentic narratives based on the following feedback data that I've received.

    Each story must follow this specific structure:
    - Situation: Exactly ONE concise sentence that sets the context with specific details about the challenge or opportunity. Be specific and quantitative where possible.
    - Task: ONE to TWO sentences clearly explaining my specific responsibilities or objectives in this situation. Focus on what I needed to accomplish.
    - Action: A BULLETED LIST of specific steps I took, focusing on MY individual contribution even in team settings. Include 4-6 concrete actions. Feel free to extrapolate reasonable details based on the information provided.
    - Result: EXACTLY THREE sentences quantifying the positive outcomes where possible and linking them directly to my actions. The first sentence should focus on immediate impacts, the second on metrics or quantifiable outcomes, and the third on longer-term or broader implications.

    IMPORTANT: Each story must strictly adhere to this structure. Do not deviate from the format or omit any required elements. Ensure that the Situation, Task, Action, and Result are clearly distinct and follow the specified guidelines.
    Guidelines needs to be extrapolated, for example, if it's a sales topic we need to talk about revenue. If it's about technical we need to focus on result for a technical.

    ${contextInfo.instructions}
    ${contextInfo.audience}`;
Then the prompt gets three more pieces. The audience you picked adds one guideline, for example "Focus on STAR stories that emphasize my ability to lead and inspire others" for leadership. Each feedback row goes in as a numbered entry, capped at 50 so the prompt stays a reasonable size. And the end of the prompt asks for a JSON array, shows two complete example stories, and says the reply must be "directly parseable by JSON.parse() without any modifications".
The JSON example was a late fix. The commit where the app first worked end to end says it "could use a JSON as an example of a story", and the next commit, "Backend Updates with Action and better Prompting", added the example and the bulleted action list.
The prompt also tells the model to "extrapolate reasonable details" and to quantify results where it can. The stories sound better for it. They can also carry numbers your feedback never mentioned. Check them against what really happened.
3. Why the parser has a fallback, and the reply that slips past it
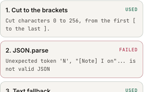
Asking for JSON doesn't guarantee JSON. A model can wrap the array in a friendly sentence, put it in a code fence, or skip JSON and write labeled paragraphs. So the response processor tries three things in order: cut from the first [ to the last ], run JSON.parse, and if that throws, fall back to a text parser that looks for Situation, Task, Action and Result labels. Whatever comes out is validated, and a story missing any part is dropped.
responseProcessor.js, lines 32 to 58
function parseAIResponse(responseText) {
    try {
        // Try to extract JSON if it's wrapped in other text
        let jsonText = responseText;

        // Look for JSON array brackets if the response contains other text
        const jsonStartIndex = responseText.indexOf('[');
        const jsonEndIndex = responseText.lastIndexOf(']');

        if (jsonStartIndex >= 0 && jsonEndIndex > jsonStartIndex) {
            jsonText = responseText.substring(jsonStartIndex, jsonEndIndex + 1);
        }

        // Parse the JSON
        const stories = JSON.parse(jsonText);

        // Validate that we have an array
        if (!Array.isArray(stories)) {
            throw new Error('Response is not a valid array');
        }

        return stories;
    } catch (error) {
        // Fallback to the text parsing method if JSON parsing fails
        return parseAIResponseText(responseText);
    }
}
Below, that same code runs in your browser. Pick an example reply on the left and the right side shows which of the four steps it went through and what the API would send back. It starts on "JSON inside prose", the everyday case the bracket cut exists for. The last example, a "[Note]" before the JSON, is the one that gets through validation as junk.
Pick a model reply
The reply from the model (editable)
Model reply to parse
The replies are examples written for this page, not real model output.
What the processor does
- 1. Cut to the brackets
- 2. JSON.parse
- 3. Text fallback
- 4. Validate each story
Your own edit: the steps above show the path it took.
[
  {
    "situation": "A client's checkout redesign was two weeks behind because design and engineering kept reworking the same screens.",
    "task": "I needed to get both teams working from one set of components before the next release.",
    "action": [
      "Audited the screens that were reworked most often.",
      "Set up a shared component library with the engineering lead.",
      "Ran a weekly review where both teams signed off on changes.",
      "Documented the rules for adding a new component."
    ],
    "result": "The next release shipped on time. Rework tickets dropped in the following sprint. The library became the starting point for the next project."
  }
]
Here are your STAR stories:

```json
[
  {
    "situation": "A new client team had little experience with the design tools we used.",
    "task": "I was asked to get them productive before the first design review.",
    "action": ["Ran two hands-on training sessions.", "Paired with each designer on a real screen.", "Wrote a one-page guide to our file conventions."],
    "result": "The team presented their own screens at the first review. Questions to our team dropped in the following weeks. The guide was reused for the next onboarding."
  }
]
```

Let me know if you want more stories!
[
  {
    "situation": "Stakeholders disagreed on the priorities for a portal redesign.",
    "task": "I had to get one agreed list before design started.",
    "action": ["Interviewed each stakeholder group.", "Ran a prioritization workshop.", "Published the agreed list."],
    "result": "Design started with one backlog. Fewer change requests came in mid-project. The workshop format was reused on other projects."
  },
  {
    "situation": "A partner team asked for help with accessibility fixes late in a release.",
    "task": "I offered to review their highest-traffic pages.",
    "action": ["Ran an audit of the top pages.", "Paired on the fixes."],
    "result": ""
  }
]
Situation: A client's mobile app had inconsistent navigation across its main sections.
Task: I needed to propose one navigation pattern the client could approve.
Action:
- Mapped the current navigation in each section.
- Sketched three options and tested them with five users.
- Presented the winning option with the test notes.
Result: The client approved the new navigation in one meeting. Development started the following sprint. The pattern was applied to the web app later.
I could not find enough feedback in the file to write a story. Could you upload more entries?
[Note] I only had a few feedback entries to work with.

Here is one story:
{
  "situation": "A design review kept slipping because feedback came in late.",
  "task": "I set out to get feedback earlier.",
  "action": ["Moved reviews to a fixed weekly slot."],
  "result": "Reviews stopped slipping. Feedback arrived on time. The slot is still on the calendar."
}
da712d5. The table lists what each example reply returns.Porting the parser to this page turned up that last case, and it's worth knowing. If the reply has a bracket before the JSON, like "[Note]", the cut grabs the wrong span, JSON.parse fails, and the text fallback finds the words "situation" and "task" inside the JSON keys. The API returns 200 with a story made of JSON fragments. Validation only checks that each part exists.
4. How five AI coding tools ranked in April 2025
I vibe coded the app, meaning I described what I wanted and let AI tools write the code. I used five of them and ranked them on four things: functional vibe, refactoring, handling outside context, and getting it right with minimal feedback. This is the ranking as I wrote it on April 13, 2025. The tools have changed a lot since, so read it as a snapshot.
@anthropic-ai/claude-code)The tool I ranked first was the one that could see the whole codebase and work in my terminal, and it was also the one that needed the least handholding. The repo's README lists four of the tools and what each one did.
Have you tried vibe coding something like this yet? I'd like to hear how it went.